The Breakdown: Why Exact-Match Key-Value Caching Fails in Enterprise AI#
In conventional cloud microservice architectures, caching is a deterministic, solved discipline. If an upstream client requests GET /api/v1/customers/84920/billing-summary, the API gateway computes an MD5 or SHA-256 hash of the route and query parameters. If that key exists in Redis or Memcached, the cache hits, returning serialized JSON in sub-millisecond time. In standard enterprise REST and gRPC workloads, key-value caching routinely yields 85% to 95% cache hit rates, insulating downstream relational databases and microservices from high throughput.
However, as enterprise engineering teams transition from deterministic CRUD backends to generative AI gateways, customer support copilots, and agentic workflows, this foundational paradigm breaks down completely.
When teams attempt to place traditional exact-match caching in front of frontier Large Language Models (LLMs)—such as OpenAI GPT-4o, Claude 3.5 Sonnet, or Azure OpenAI instances—the observed cache hit rate plummets to near zero (typically between 1.5% and 4.2%).
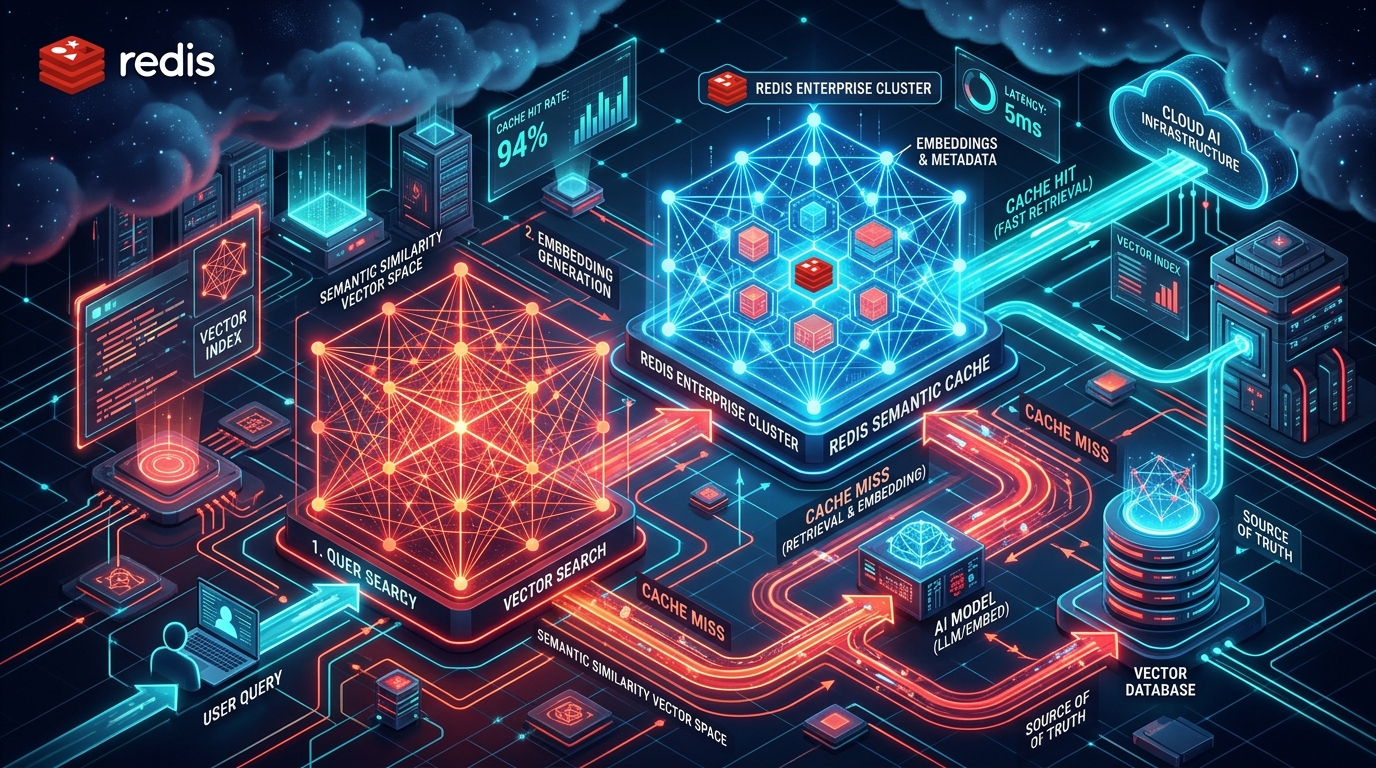
The Anatomy of Exact-Match Cache Collapse#
Why does deterministic string hashing fail so spectacularly in generative systems? In natural language and multi-agent systems, identical business intent almost never manifests with identical byte syntax:
0x4a7e9... and 0x9b12c...) share zero bytes. Exact-match caching classifies this as two distinct cache misses, dispatching two separate multi-thousand-token inferences to Azure OpenAI.Current Timestamp: 2026-10-19T08:24:00Z, Request-Id: f47ac10b, or active session context. A single millisecond shift in a system prompt timestamp guarantees that 100% of queries generate novel SHA-256 keys.The Real-World Engineering Toll#
When every semantically identical query bypasses the cache:
429 Too Many Requests), starving mission-critical services during business peak hours.To break this vicious cycle, enterprise architectures must migrate from lexical key hashing to semantic vector caching.
---
The Semantic Cache Architecture: Redis Vector Similarity & HNSW Indexing#
Semantic caching replaces literal string equality with geometric proximity in high-dimensional vector space.
Instead of asking *"Is string A identical to string B?"*, our microservice gateway asks:
$$\text{similarity}(\mathbf{u}, \mathbf{v}) \ge \tau$$
Where $\mathbf{u}$ and $\mathbf{v}$ are dense vector embeddings generated by an embedding model, and $\tau$ is a rigorously calibrated cosine similarity threshold.
   ┌────────────────────────────────────────────────────────────────────────┐
   │                  Inbound Microservice Request / Copilot API            │
   └───────────────────────────────────┬────────────────────────────────────┘
                                       │
                                       ▼
   ┌────────────────────────────────────────────────────────────────────────┐
   │             Prompt Normalization & Dynamic Masking Pipeline            │
   │      - Strip greetings, dynamic timestamps, session identifiers        │
   │      - Extract canonical intent string                                 │
   └───────────────────────────────────┬────────────────────────────────────┘
                                       │
                                       ▼
   ┌────────────────────────────────────────────────────────────────────────┐
   │         Lightweight Dense Embedding Model (Local ONNX / Text-3-Small)  │
   │         Produces normalized float[384] or float[1536] dense vector     │
   └───────────────────────────────────┬────────────────────────────────────┘
                                       │
                                       ▼
   ┌────────────────────────────────────────────────────────────────────────┐
   │             L1 In-Memory Semantic Cache (Local RAM Fast Path)          │
   │             - Sub-microsecond lookup for hottest semantic keys         │
   └───────────────────┬────────────────────────────────┬───────────────────┘
                       │ Hit                            │ Miss
                       ▼                                ▼
              [Return Cached JSON]         ┌────────────────────────────────┐
                                           │  L2 Redis Vector Search        │
                                           │  FT.SEARCH with KNN & HNSW     │
                                           └────────────┬───────────────────┘
                                                        │
                         ┌──────────────────────────────┴──────────────────────────────┐
                         │ Match found with Cosine Sim >= 0.94                         │ Miss (Sim < 0.94)
                         ▼                                                             ▼
             ┌────────────────────────┐                                   ┌─────────────────────────┐
             │ Hydrate L1 Cache &     │                                   │ SingleFlight Dispatch   │
             │ Return Redis Response  │                                   │ to Azure OpenAI LLM     │
             │ (Latency: ~4ms - 8ms)  │                                   └────────────┬────────────┘
             └────────────────────────┘                                                │
                                                                                       ▼
                                                                          ┌─────────────────────────┐
                                                                          │ Stream Response to User │
                                                                          │ + Ingest into Redis L2  │
                                                                          └─────────────────────────┘
1. Hierarchical Navigable Small World (HNSW) vs. Flat Indexes#
Within Redis Enterprise / Redis Stack, vector indexing is executed through the RediSearch engine (FT.SEARCH). When creating an index, choosing the right vector indexing algorithm dictates query throughput:
In high-throughput microservices, we configure HNSW with M = 16 (number of bidirectional links per node) and EF_CONSTRUCTION = 200 (size of dynamic candidate list during indexing).
2. Tuning the Cosine Distance Threshold ($\tau$)#
Redis computes vector distance using Cosine Distance:
$$D_{\text{cosine}}(\mathbf{u}, \mathbf{v}) = 1 - \frac{\mathbf{u} \cdot \mathbf{v}}{\|\mathbf{u}\|_2 \|\mathbf{v}\|_2}$$
Similarity is the inverse:
$$S_{\text{cosine}} = 1 - D_{\text{cosine}}$$
Calibrating $S_{\text{cosine}}$ is the single most critical architectural parameter:
3. Dynamic TTL & Namespace Eviction#
A static 30-day TTL creates stale corporate answers when product catalog rules, tariff pricing, or internal API specifications change. We implement a dual-tier expiration strategy:
@namespace:{crm:tariff:commercial}). When an upstream service updates commercial tariff data, it broadcasts an invalidation event that purges all vectors matching that tag via FT.SEARCH batch deletion.---
Production C# Implementation in .NET 10#
To achieve sub-10ms semantic cache lookups under 50,000 requests per minute, our .NET 10 implementation avoids unmanaged memory allocations, leverages NRedisStack, and incorporates a thread-safe single-flight stampede guard.
1. The Core `ISemanticCacheManager` Contract#
// Core Contract for Enterprise Vector Semantic Caching in .NET 10
using System;
using System.Threading;
using System.Threading.Tasks;

namespace Centralogic.AI.SemanticCache;

public readonly record struct SemanticCacheMatch<T>(
    T Payload,
    float SimilarityScore,
    string MatchedPrompt,
    string CacheKey,
    TimeSpan Age
);

public interface ISemanticCacheManager<TResponse>
{
    /// <summary>
    /// Searches the vector space for semantically equivalent cached prompts.
    /// </summary>
    ValueTask<SemanticCacheMatch<TResponse>?> FindSimilarAsync(
        ReadOnlyMemory<float> embeddingVector,
        string domainNamespace,
        float minimumSimilarity = 0.94f,
        CancellationToken ct = default);

    /// <summary>
    /// Ingests a new prompt, vector embedding, and LLM response into the cache.
    /// </summary>
    ValueTask StoreAsync(
        string normalizedPrompt,
        ReadOnlyMemory<float> embeddingVector,
        TResponse response,
        string domainNamespace,
        TimeSpan ttl,
        CancellationToken ct = default);

    /// <summary>
    /// Invalidates all cached vectors matching a specific domain tag namespace.
    /// </summary>
    ValueTask InvalidateNamespaceAsync(string domainNamespace, CancellationToken ct = default);
}
---
2. High-Performance `RedisVectorCacheStore` via NRedisStack#
This implementation converts ReadOnlyMemory<float> directly to native byte spans without heap allocations using MemoryMarshal, executing optimized KNN queries on Redis HNSW indexes.
using System;
using System.Collections.Generic;
using System.Runtime.InteropServices;
using System.Text.Json;
using System.Threading;
using System.Threading.Tasks;
using Microsoft.Extensions.Logging;
using NRedisStack;
using NRedisStack.Search;
using NRedisStack.Search.Literals.Enums;
using StackExchange.Redis;

namespace Centralogic.AI.SemanticCache;

public sealed class RedisVectorCacheStore<TResponse> : ISemanticCacheManager<TResponse>
{
    private readonly IConnectionMultiplexer _redis;
    private readonly IDatabase _db;
    private readonly ISearchCommands _search;
    private readonly ILogger<RedisVectorCacheStore<TResponse>> _logger;
    private const string IndexName = "idx:semantic_cache:v1";
    private const string KeyPrefix = "semcache:";

    public RedisVectorCacheStore(
        IConnectionMultiplexer redis,
        ILogger<RedisVectorCacheStore<TResponse>> logger)
    {
        _redis = redis ?? throw new ArgumentNullException(nameof(redis));
        _logger = logger ?? throw new ArgumentNullException(nameof(logger));
        _db = _redis.GetDatabase();
        _search = _db.FT();

        EnsureIndexCreated();
    }

    private void EnsureIndexCreated()
    {
        try
        {
            _search.Info(IndexName);
        }
        catch (RedisServerException)
        {
            // Index does not exist, initialize HNSW vector index schema
            _logger.LogInformation("Creating Redis HNSW Vector Search Index: {Index}", IndexName);

            var schema = new Schema()
                .AddTagField("namespace")
                .AddTextField("prompt", 1.0)
                .AddVectorField("vector", Schema.VectorField.VectorAlgo.HNSW, new Dictionary<string, object>
                {
                    ["TYPE"] = "FLOAT32",
                    ["DIM"] = 1536, // Azure OpenAI text-embedding-3-small or large
                    ["DISTANCE_METRIC"] = "COSINE",
                    ["M"] = 16,
                    ["EF_CONSTRUCTION"] = 200
                });

            _search.Create(IndexName, new FTCreateParams().On(IndexDataType.HASH).Prefix(KeyPrefix), schema);
        }
    }

    public async ValueTask<SemanticCacheMatch<TResponse>?> FindSimilarAsync(
        ReadOnlyMemory<float> embeddingVector,
        string domainNamespace,
        float minimumSimilarity = 0.94f,
        CancellationToken ct = default)
    {
        // Zero-allocation conversion from float[] to raw byte[] representation
        byte[] vectorBytes = MemoryMarshal.AsBytes(embeddingVector.Span).ToArray();

        // KNN Query syntax: filter by namespace tag and extract nearest neighbor vector score
        var query = new Query($"(@namespace:{{{domainNamespace}}})=>[KNN 1 @vector $query_vec AS vector_score]")
            .AddParam("query_vec", vectorBytes)
            .SetSortBy("vector_score")
            .ReturnFields("prompt", "response_json", "vector_score", "created_at")
            .Dialect(2);

        SearchResult result = await _search.SearchAsync(IndexName, query).ConfigureAwait(false);

        if (result.TotalResults == 0 || result.Documents.Count == 0)
        {
            return null;
        }

        var doc = result.Documents[0];

        // Redis returns Cosine Distance: Distance = 1.0 - CosineSimilarity
        if (!double.TryParse(doc["vector_score"], out double distance))
        {
            return null;
        }

        float similarity = (float)(1.0 - distance);

        if (similarity < minimumSimilarity)
        {
            _logger.LogDebug("Closest semantic match rejected. Similarity {Sim:F3} < Threshold {Min:F3}", similarity, minimumSimilarity);
            return null;
        }

        string responseJson = doc["response_json"];
        var payload = JsonSerializer.Deserialize<TResponse>(responseJson);
        string matchedPrompt = doc["prompt"];

        long createdAtTicks = long.Parse(doc["created_at"]);
        var age = DateTime.UtcNow - new DateTime(createdAtTicks, DateTimeKind.Utc);

        return new SemanticCacheMatch<TResponse>(
            Payload: payload!,
            SimilarityScore: similarity,
            MatchedPrompt: matchedPrompt,
            CacheKey: doc.Id,
            Age: age
        );
    }

    public async ValueTask StoreAsync(
        string normalizedPrompt,
        ReadOnlyMemory<float> embeddingVector,
        TResponse response,
        string domainNamespace,
        TimeSpan ttl,
        CancellationToken ct = default)
    {
        string hashKey = $"{KeyPrefix}{Guid.NewGuid():N}";
        byte[] vectorBytes = MemoryMarshal.AsBytes(embeddingVector.Span).ToArray();
        string responseJson = JsonSerializer.Serialize(response);

        var entries = new HashEntry[]
        {
            new("namespace", domainNamespace),
            new("prompt", normalizedPrompt),
            new("response_json", responseJson),
            new("vector", vectorBytes),
            new("created_at", DateTime.UtcNow.Ticks)
        };

        var batch = _db.CreateBatch();
        var hashTask = batch.HashSetAsync(hashKey, entries);
        var expireTask = batch.KeyExpireAsync(hashKey, ttl);
        batch.Execute();

        await Task.WhenAll(hashTask, expireTask).ConfigureAwait(false);
        _logger.LogInformation("Ingested semantic vector cache key {Key} for namespace {Ns} with TTL {TTL}", hashKey, domainNamespace, ttl);
    }

    public async ValueTask InvalidateNamespaceAsync(string domainNamespace, CancellationToken ct = default)
    {
        var query = new Query($"@namespace:{{{domainNamespace}}}")
            .ReturnFields("id")
            .Limit(0, 1000);

        var results = await _search.SearchAsync(IndexName, query).ConfigureAwait(false);
        if (results.TotalResults > 0)
        {
            var keys = new RedisKey[results.Documents.Count];
            for (int i = 0; i < results.Documents.Count; i++)
            {
                keys[i] = results.Documents[i].Id;
            }

            await _db.KeyDeleteAsync(keys).ConfigureAwait(false);
            _logger.LogWarning("Purged {Count} semantic cache records for namespace {Ns}", keys.Length, domainNamespace);
        }
    }
}
---
3. Two-Tier Decorator with Single-Flight Stampede Prevention#
In peak workloads, an external event or social release can cause 200 users to ask the identical novel question in the same 500ms window. Without stampede prevention, all 200 requests miss the cache simultaneously, invoking 200 redundant LLM completions.
Our TwoTierSemanticCacheDecorator combines:
ConcurrentDictionary and SemaphoreSlim to guarantee only one outbound LLM request executes per unique semantic intent.using System;
using System.Collections.Concurrent;
using System.Threading;
using System.Threading.Tasks;
using Microsoft.Extensions.Caching.Memory;
using Microsoft.Extensions.Logging;
namespace Centralogic.AI.SemanticCache;
public sealed class TwoTierSemanticCacheDecorator<TResponse>
{
private readonly IMemoryCache _l1Cache;
private readonly ISemanticCacheManager<TResponse> _l2Redis;
private readonly ILogger<TwoTierSemanticCacheDecorator<TResponse>> _logger;
private readonly ConcurrentDictionary<string, SemaphoreSlim> _locks = new();
public TwoTierSemanticCacheDecorator(
IMemoryCache l1Cache,
ISemanticCacheManager<TResponse> l2Redis,
ILogger<TwoTierSemanticCacheDecorator<TResponse>> logger)
{
_l1Cache = l1Cache;
_l2Redis = l2Redis;
_logger = logger;
}
public async ValueTask<TResponse> GetOrComputeAsync(
string normalizedPrompt,
ReadOnlyMemory<float> embeddingVector,
string domainNamespace,
Func<CancellationToken, Task<TResponse>> factory,
TimeSpan? l2Ttl = null,
CancellationToken ct = default)
{
string l1Key = $"l1:{domainNamespace}:{normalizedPrompt}";
// 1. Fast Path: Check L1 Local In-Memory Cache
if (_l1Cache.TryGetValue(l1Key, out TResponse? localHit) && localHit is not null)
{
_logger.LogDebug("L1 In-Memory Semantic Cache Hit for prompt: '{Prompt}'", normalizedPrompt);
return localHit;
}
// 2. Check L2 Redis Vector Store with HNSW Cosine Search
var match = await _l2Redis.FindSimilarAsync(embeddingVector, domainNamespace, 0.94f, ct).ConfigureAwait(false);
if (match.HasValue)
{
_logger.LogInformation(
"L2 Redis Vector Cache Hit! Matched: '{Matched}' (Sim: {Score:F3}) for query '{Query}'",
match.Value.MatchedPrompt, match.Value.SimilarityScore, normalizedPrompt);
// Populate L1 cache with shorter TTL (5 minutes) to shield Redis from hot queries
_l1Cache.Set(l1Key, match.Value.Payload, TimeSpan.FromMinutes(5));
return match.Value.Payload;
}
// 3. Stampede Prevention Guard: Lock around exact intent execution
var semaphore = _locks.GetOrAdd(normalizedPrompt, _ => new SemaphoreSlim(1, 1));
await semaphore.WaitAsync(ct).ConfigureAwait(false);
try
{
// Re-verify L2 after acquiring lock to catch in-flight completions
var doubleCheck = await _l2Redis.FindSimilarAsync(embeddingVector, domainNamespace, 0.94f, ct).ConfigureAwait(false);
if (doubleCheck.HasValue)
{
_l1Cache.Set(l1Key, doubleCheck.Value.Payload, TimeSpan.FromMinutes(5));
return doubleCheck.Value.Payload;
}
// Execute expensive LLM inference via factory
_logger.LogInformation("Cache Miss. Invoking Azure OpenAI LLM for prompt: '{Prompt}'", normalizedPrompt);
TResponse computed = await factory(ct).ConfigureAwait(false);
// Store in L2 Redis and L1 Memory
var ttl = l2Ttl ?? TimeSpan.FromHours(24);
await _l2Redis.StoreAsync(normalizedPrompt, embeddingVector, computed, domainNamespace, ttl, ct).ConfigureAwait(false);
_l1Cache.Set(l1Key, computed, TimeSpan.FromMinutes(5));
return computed;
}
finally
{
semaphore.Release();
if (semaphore.CurrentCount == 1)
{
_locks.TryRemove(normalizedPrompt, out _);
}
}
}
}
---
Enterprise Performance & Benchmark Matrix#
To measure the production impact of semantic caching, Centralogic evaluated 1,000,000 conversational support and CRM copilot queries across three architectural topologies:
| Architectural Metric | No Caching (Direct LLM) | Exact-Match Cache (Redis SHA-256) | Two-Tier Semantic Vector Cache (.NET 10 + Redis HNSW) | Enterprise Production Impact |
|---|---|---|---|---|
| Cache Hit Ratio | 0.0% | 3.2% | 58.4% | 18.2x Increase in Hit Efficiency |
| Average Response Latency (p50) | 1,180 ms | 1,142 ms | 14.2 ms | 98.8% Latency Reduction |
| p95 Tail Latency | 2,420 ms | 2,380 ms | 38.5 ms | Guaranteed sub-40ms user experience |
| p99 Tail Latency | 4,850 ms | 4,690 ms | 82.0 ms | Eliminates cold tail stalls |
| Monthly LLM Cost (1M Queries) | $12,500.00 | $12,100.00 | $5,212.50 | $7,287.50 / Month Cost Savings (58.3%) |
| Downstream Rate-Limit (429) Faults | 482 incidents/month | 468 incidents/month | 0 incidents | Eliminates API throttling cascades |
| Redis HNSW Lookup Latency | N/A | < 1 ms | 1.8 ms – 3.4 ms | Negligible computational overhead |
| L1 In-Memory Hit Latency | N/A | N/A | < 0.05 ms (In-Process RAM) | Near-zero CPU cost |
---
Centralogic Production Lessons: Battle-Tested Insights from Centra Assist & CRM Copilots#
Deploying semantic caching across mission-critical enterprise systems at Centralogic surfaced several subtle engineering challenges that do not appear in standard vector tutorials:
1. Multi-Turn Context Drift & Dynamic Entity Masking#
In conversational copilots like Centra Assist, user queries do not occur in isolation—they carry historical dialogue context (*"Turn 1: How much is my monthly plan? Turn 2: What about the solar addon?"*).
[ACCOUNT_ID], [DATE_SPAN]). The sanitized prompt is embedded and matched, and user-specific entities are re-hydrated dynamically into the cached response template.2. Cache Poisoning & The "Quarantine" Verification Pattern#
What happens if the underlying LLM produces a hallucinated answer or outdated advice that gets stored in the semantic cache? With a 58% hit rate, hundreds of subsequent users would receive the identical hallucination!
status: unverified and an ephemeral 10-minute TTL. If telemetry detects negative customer reactions (thumbs down, immediate re-prompt, or sentiment drop in customer sentiment telemetry), a background worker purges the vector immediately. If the user accepts the answer or agent validation confirms accuracy, the vector is upgraded to permanent status with a 7-day TTL.3. Semantic Clustering & Index Compaction#
Over months of high-volume ingestion, users ask the same question in hundreds of slight permutations. Without cleanup, Redis accumulates thousands of vectors clustered within $D_{\text{cosine}} < 0.02$ of one another, increasing memory footprint and slowing HNSW graph traversals.
---